Qwen4-Max-Preview Release: 1M Context, No Benchmarks Yet
Alibaba Qwen has released a preview of its next flagship model as Qwen4-Max-Preview, model ID qwen4-max-preview. The official QwenCloud documentation lists a 1M token context and a maximum output of 393,216 tokens, a budget that reasoning traces and the final answer share. Access is narrow for now: the model is available only through a Token Plan subscription, and Alibaba has published no benchmarks or model card for it.
That combination defines the release. The specifications are concrete enough to plan around, while the performance question is left entirely to the teams who try it. Qwen says world knowledge, code generation and sustained performance on long tool calling tasks have improved over Qwen3.8, but none of those claims comes with a number yet, so they read as direction rather than evidence.
Specifications From the Official Documentation
The model accepts text, image and video input, covering screen capture analysis, document understanding and video analysis. Reasoning is on by default, and reasoning_effort selects low, medium or xhigh, with xhigh as the default. A default at the top of the range is a practical warning as much as a feature: long reasoning traces draw from the same 393,216 token output budget as the answer, so cost and latency control will depend on teams lowering the effort setting for routine work instead of accepting the default everywhere.
Compatibility is the other half of the specification sheet. The API supports OpenAI Chat Completions, Responses and Anthropic Messages, plus Function Calling, web search, built in tools and structured output in JSON Object and JSON Schema forms. In practical terms, the model is designed to be evaluated inside an existing agent stack rather than through a new integration, which shortens the path from announcement to a real comparison on a team own repository.
Access Through Token Plan and Existing Coding Clients
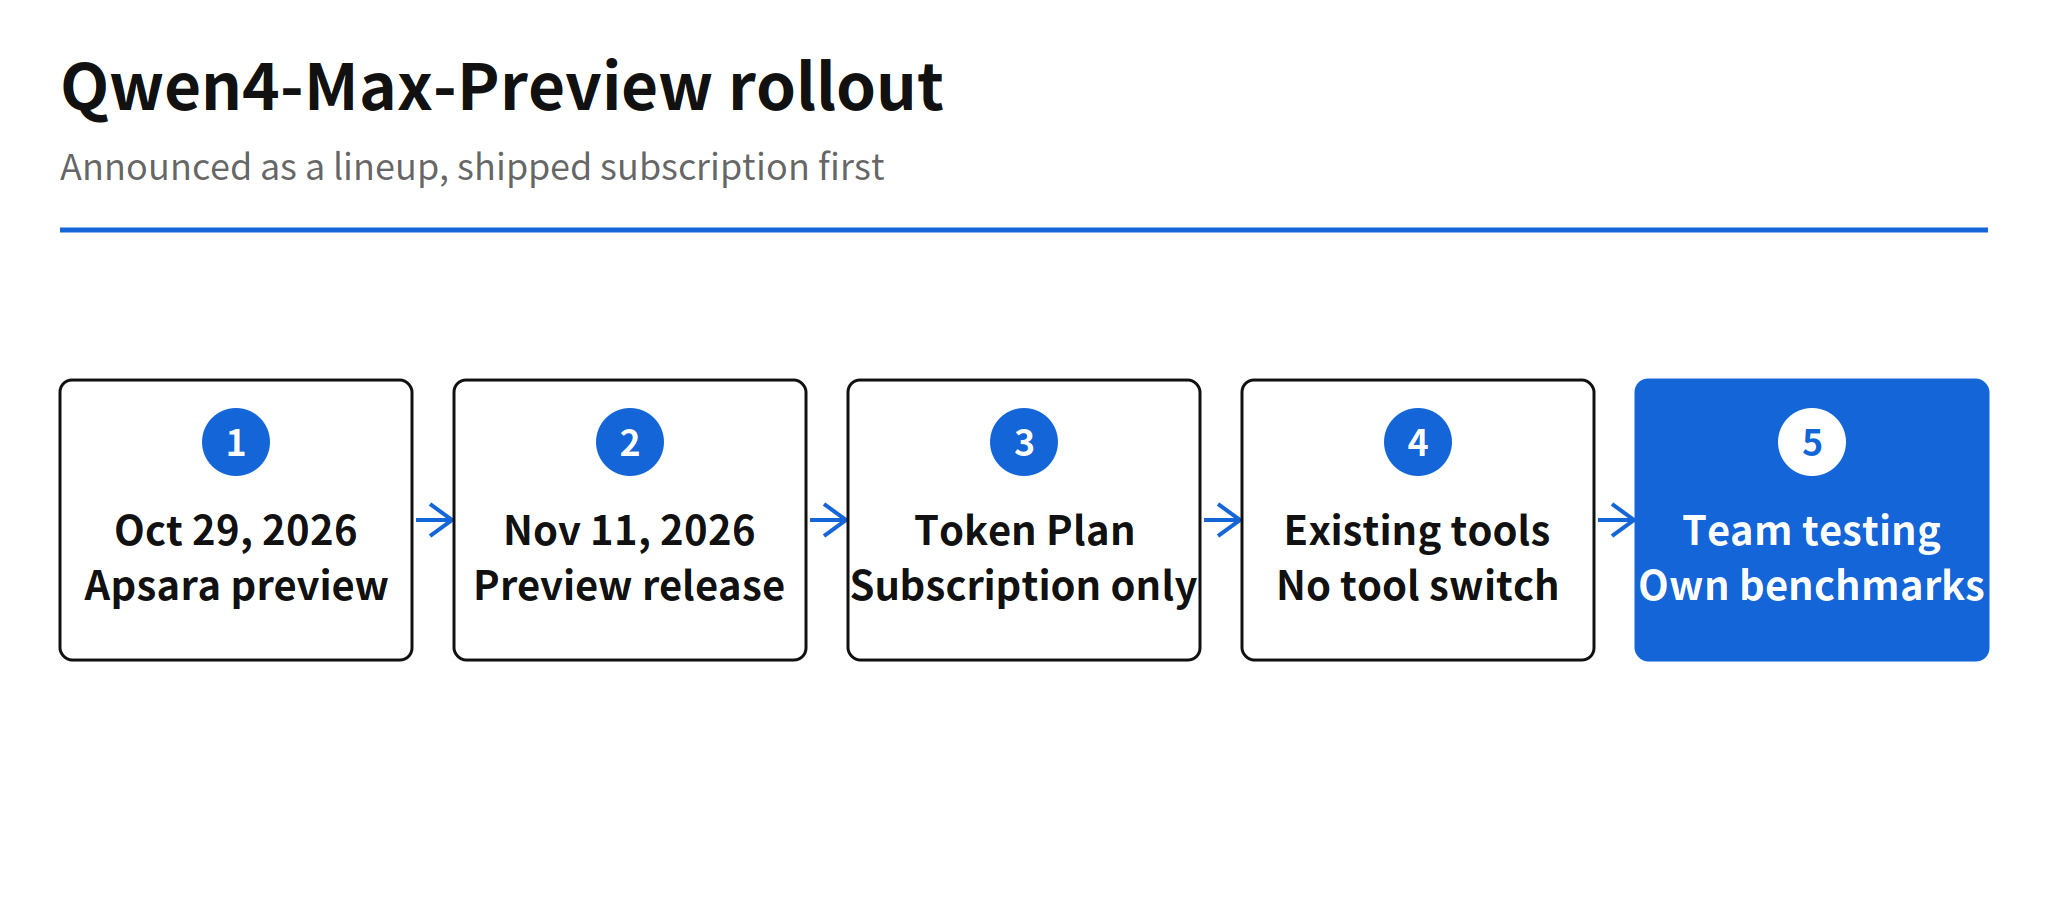
The Token Plan dedicated base URL is https://token-plan.maas.qwencloudapi.com. Because the endpoint speaks the OpenAI and Anthropic protocols, Qwen Code, Cline, Claude Code, Cursor, OpenCode and Codex can connect to it directly. New user pricing starts at about $3 for the entry tier, according to AlphaSignal, and plans allow between 1 and 8 concurrent agents depending on the tier. Access is also widening toward QwenWork, Qoder, Qwen App and QwenStudio.
The subscription first route changes who can evaluate the model and how. A team already paying for a coding agent can add the preview for the price of a coffee and run it against its own tasks the same day, with no procurement step and no migration. The limit is just as clear: there is no pay as you go API price and no general release date, so production planning, cost forecasting and any workload that needs contractual terms have to wait for a later announcement.
Background From the Apsara Lineup Preview
The Qwen4 family was first previewed on October 29, 2026 at the Apsara Conference in Amsterdam, where Qwen4-Max, Qwen4-Flash, Qwen4-Plus and Qwen4-27B were announced as a lineup. This preview is the first of those models to reach users. The rest of the lineup has no release dates in the material published so far, which makes the Max preview the only concrete signal about how the generation will be packaged: subscription access and client compatibility first, weights and detailed documentation later, if at all.
The Missing Benchmarks and the Previous Generation Baseline
No Qwen4-Max benchmark exists yet. The only scores available for orientation belong to the previous generation, Qwen3.8-Max: Terminal Bench 2.1 at 86.6, SWE-bench Pro at 67.7, PaperBench at 93.0 and CoWorkBench at 74.8, as reported by AlphaSignal. Those numbers set the bar the new model has to clear, and they also show why a claim of improvement without a table is hard to use. A generational step could be large or marginal, and nothing published so far distinguishes the two.
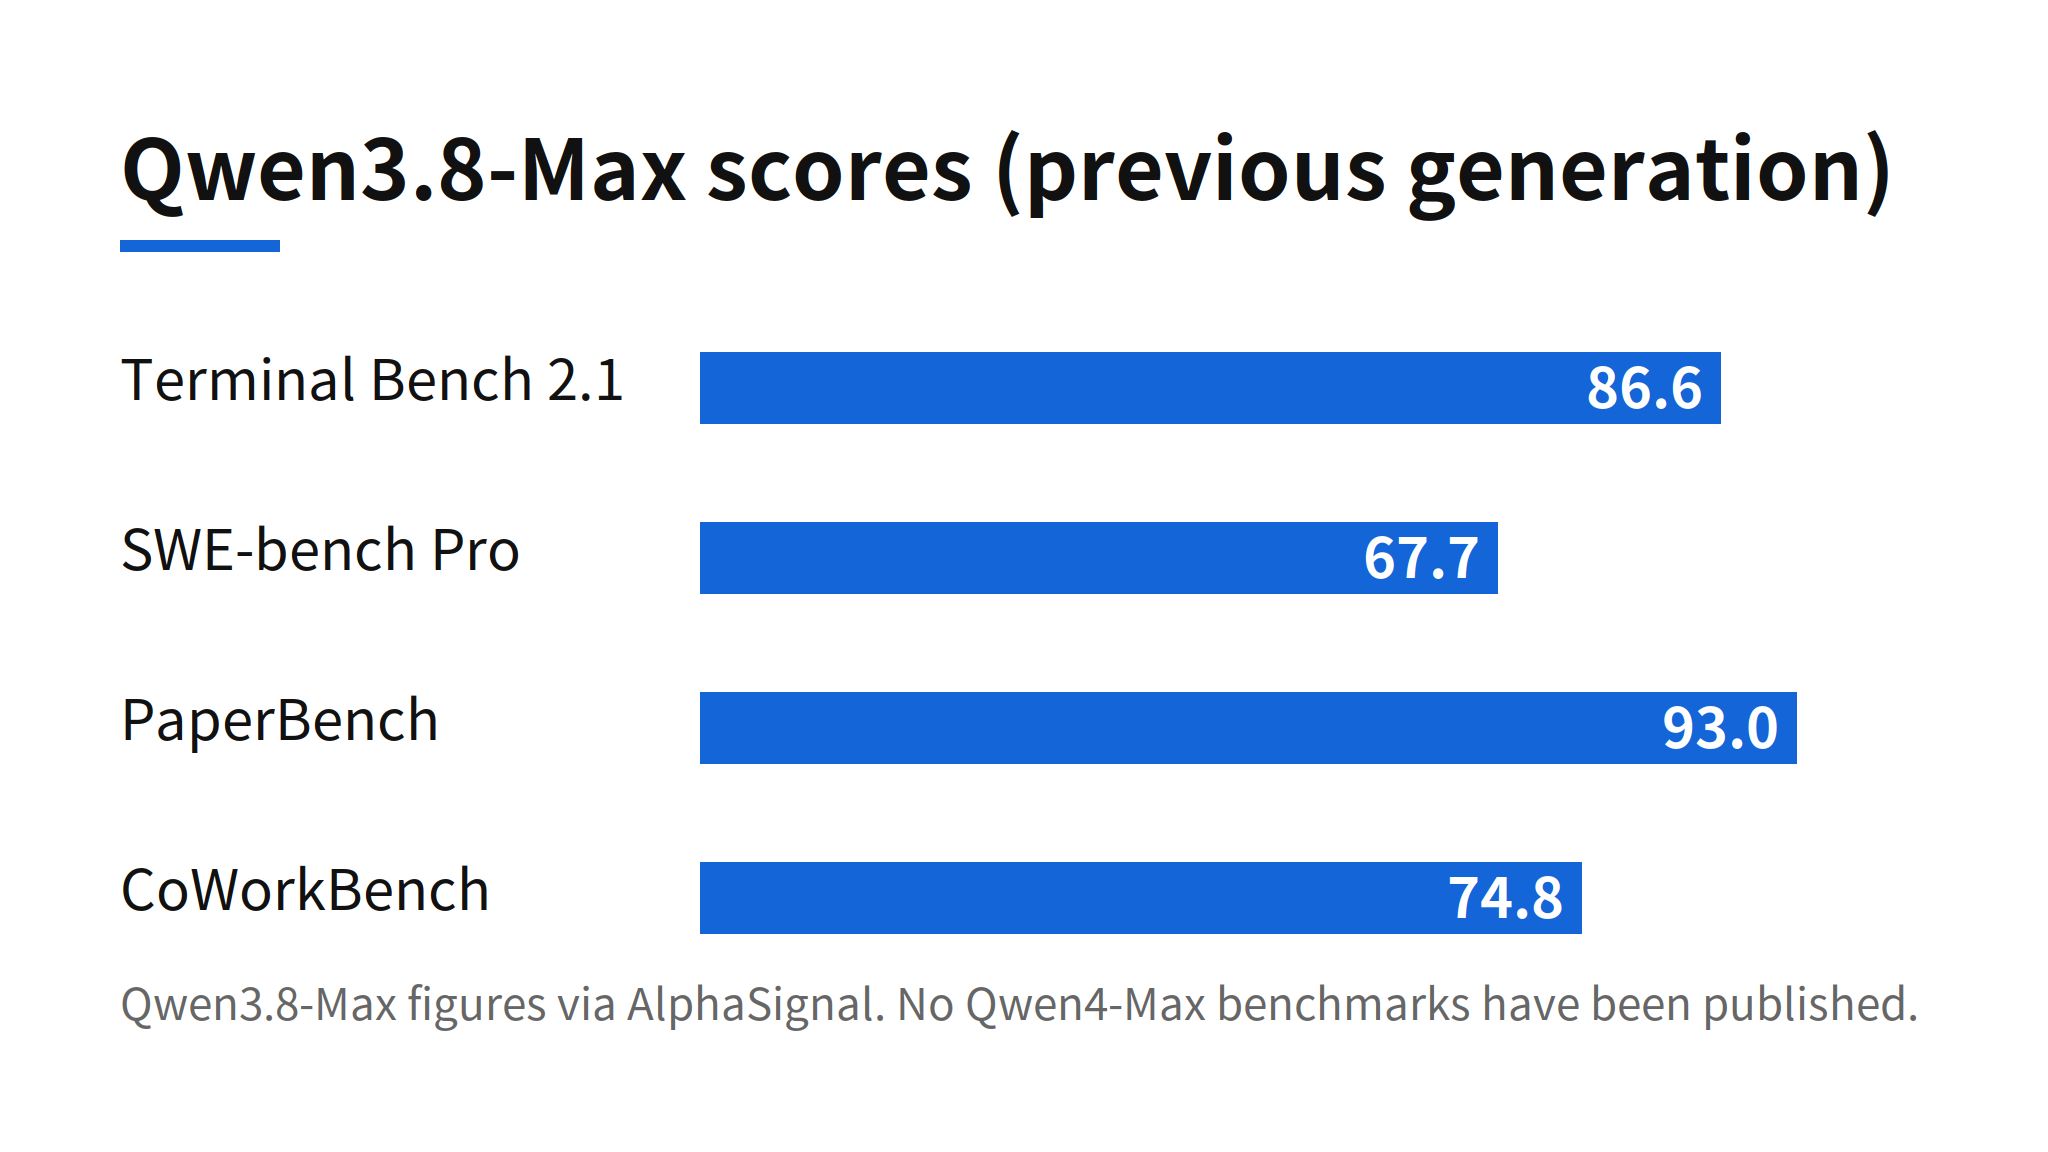
The chart above shows Qwen3.8-Max results, not Qwen4-Max results. Alibaba states that the 1M token context figure comes from its own documentation, and it also notes that a client side setting is not proof that the full context is usable in practice. Parameter count, downloadable weights, a self-hosting license, a general release date and pay as you go pricing are all undisclosed.
For a flagship line that built its reputation partly on open weights, the silence on weights matters. Teams that self-host Qwen models cannot plan a migration from this announcement, and teams that cannot send code to a hosted subscription endpoint are excluded from the preview entirely. Whether Qwen4 follows the open weight pattern of earlier generations is, at this point, an open question rather than a safe assumption.
Why the Qwen4-Max-Preview Release Matters
The launch sequence itself is the story. A new flagship normally arrives with a benchmark table and a model card, and the evaluation debate follows the published numbers. Here the order is reversed: subscription access and drop in compatibility with Claude Code, Cursor and Codex come first, and verification is delegated to each team running the model on its own work. That is a cheaper launch for the vendor and a more honest test for the buyer, provided teams actually run it. Until Alibaba publishes its own measurements, the useful comparison is not Qwen4 against a leaderboard. It is Qwen4 against the model a team already pays for, on the repository that team ships.
FAQ
What is Qwen4-Max-Preview?
Qwen4-Max-Preview is the preview release of Alibaba Qwen next flagship model, under the model ID qwen4-max-preview. QwenCloud documentation lists a 1M token context and a maximum output of 393,216 tokens, with text, image and video input.
How can developers access Qwen4-Max-Preview?
Access is currently through a Token Plan subscription only, using the dedicated base URL https://token-plan.maas.qwencloudapi.com. The API is compatible with OpenAI Chat Completions, Responses and Anthropic Messages, so existing clients such as Claude Code, Cursor and Codex can connect without a tool switch.
How much does Qwen4-Max-Preview cost?
Token Plan pricing for new users starts at about $3 for the entry tier, according to AlphaSignal, and plans allow between 1 and 8 concurrent agents depending on the tier. Pay as you go API pricing and a general release date have not been published.
Are there benchmarks for Qwen4-Max?
No. Alibaba has published no Qwen4-Max benchmarks or model card yet. The available scores, including Terminal Bench 2.1 at 86.6 and SWE-bench Pro at 67.7, belong to the previous generation Qwen3.8-Max and say nothing measured about the new model.
Can Qwen4-Max be self-hosted?
Not on current information. No parameter count, downloadable weights or self-hosting license has been disclosed, so the preview is a hosted subscription model for now.
Related Reading
- ERNIE 5.5 Flash Preview: Release, Pricing and Game Demo (another preview first flagship release)
- BotPsy 0.8B Release: On-Device Agent Scores and Limits