Hallmark vs Impeccable: Which Design Skill Fits the Job
Hallmark and Impeccable are the two most starred design skills for coding agents this week, and the first independent tests now separate them by job. Hallmark fits building a new landing page from scratch. Impeccable fits polishing an existing screen before it ships. That split comes from a Threads curation of user reviews published on November 3, 2026, plus two quantitative tests, one per skill, that earlier coverage of both tools had been missing.
The context matters because both skills were already popular before anyone measured them. Impeccable, by pbakaus, holds 101,543 GitHub stars and gained about 12,000 in the week covered. Hallmark, by Nutlope (Hassan El Mghari of Together AI), holds 46,985 stars and gained about 11,500 in the same week. Star counts say people installed them. The tests below say what changed when they did, and what it cost.
Two Skills, Two Different Jobs
Both skills install into a coding agent and steer it away from patterns that make a page look AI generated: a small caps label above the title, an empty photo box, a purple gradient. They attack that problem from opposite ends. Hallmark works at build time, offering 50 themes in version 2 plus redesign and audit commands, and filters patterns with its sloplint checker as the page is produced. Impeccable works as direction plus inspection, with 24 commands and 62 detection rules, and its detector runs without any LLM calls.
| Axis | Hallmark | Impeccable |
|---|---|---|
| Main use in reviews | Building a new landing page | Polishing an existing screen before shipping |
| Method | 50 themes and sloplint checks at build time | 24 commands for direction, 62 detection rules for inspection |
| Quantitative test | Landing build 44 seconds to 3 minutes 32 seconds, cost $0.16 to $0.87 (AI Parabellum) | Blind review 6.75 points, against 5.25 with no skill (Medium, AI Pruner) |
| Install | npx skills add nutlope/hallmark -g | npx impeccable install |
| License and stars | MIT, 46,985 stars | Apache-2.0, 101,543 stars |
Star counts and licenses are GitHub API figures measured on November 4, 2026. The test figures in the table are claims by each test author, and the next two sections keep them attached to their sources, because the caveats change how far each number travels.
Hallmark Test: A Better First Screen at a Higher Cost
AI Parabellum tested Hallmark 2.0.0 in Claude Code on October 29, 2026, building the same landing page twice, once with no skill and once with Hallmark on. The visible tells largely disappeared. Small caps eyebrow labels above titles dropped from 6 to 0, and real photos with credited sources replaced the empty image boxes. Under Hallmark own sloplint checker, the no skill page failed 21 checks while the Hallmark page passed every one.
The price was time, money, and turns. Build time rose from 44 seconds to 3 minutes 32 seconds, estimated cost rose from $0.16 to $0.87, and agent turns rose from 2 to 30. The often quoted summary, roughly five times the time and cost, traces back to this single test. The Threads curation repeated it, so it counts as one independent source, not two.
The test author also flagged the limits of the win. The sloplint score is graded against Hallmark own rules, and some failed items are house style choices, such as a ban on dashes in copy, rather than defects. The chosen theme picked a headline font the author judged off brand, and checking the mobile layout needed Chrome and puppeteer-core installed separately. Read together, the test supports a narrow claim: Hallmark raises the polish of a first screen, and the bill for that polish is real.
Impeccable Test: Accessibility Gains and Blind Review Scores
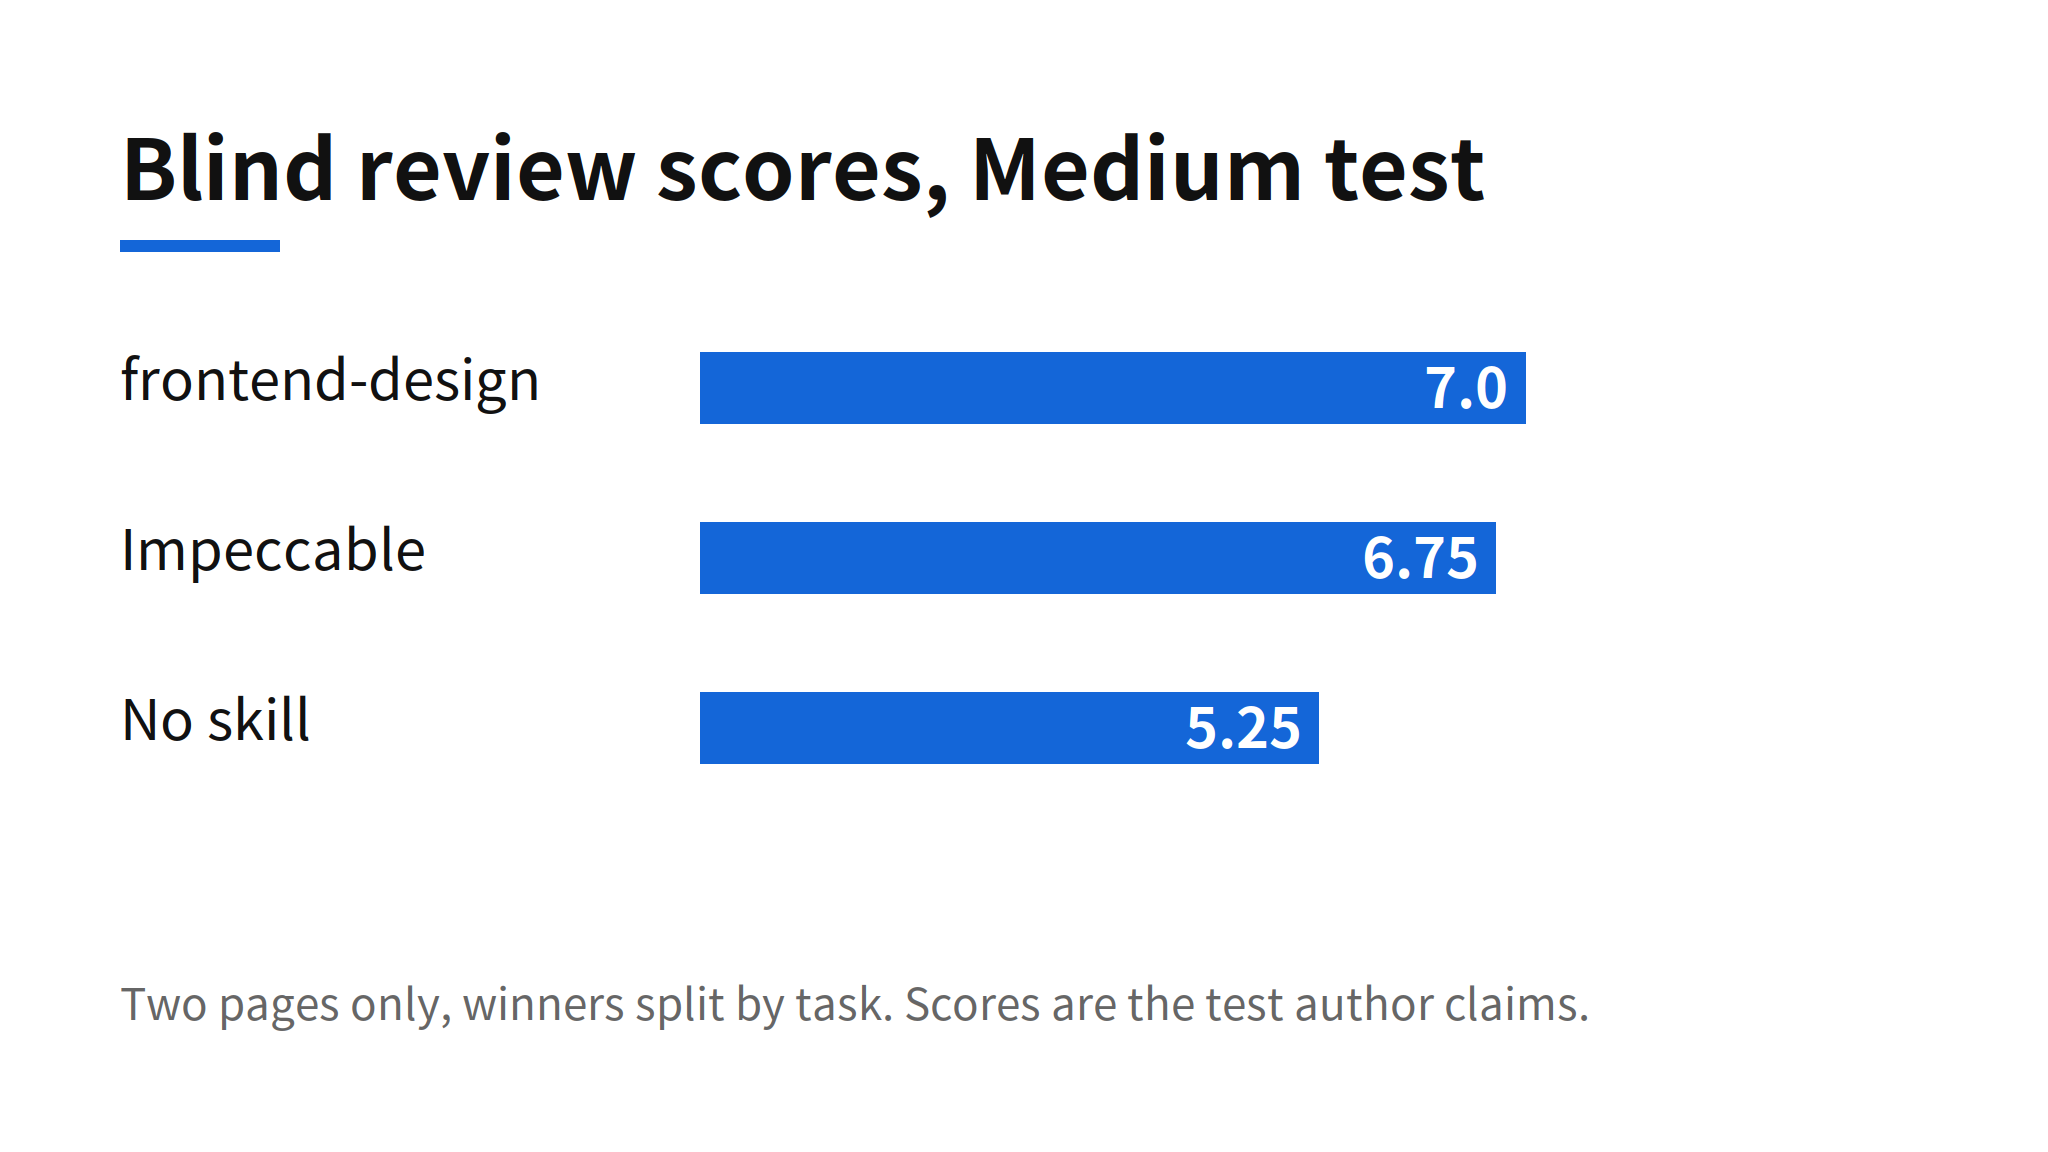
AI Pruner, writing on Medium, built two web pages with the same model under three conditions: no skill, Impeccable, and Anthropic frontend-design skill. Blind reviewers gave Impeccable pages an average of 6.75, against 5.25 for no skill and 7.0 for frontend-design. Impeccable and frontend-design split the individual tasks, one win each, so the result is an edge over doing nothing, not a lead over the other skill in the test.
The stronger result is countable. On a dental admin page, accessibility violations fell from 106 with no skill to 0 with Impeccable. That is the kind of defect a detector can enumerate, and it matches where reviewers say Impeccable earns its keep: an existing screen, late in the process, with concrete flaws to remove. The author is explicit about the sample, though. Two pages is two pages, and the winner changed between review rounds.
A Head to Head Test With Both Checkers
One gap runs through both tests above: each skill was measured alone. To close part of it, the same Brewlog brief used by AI Parabellum, an office coffee subscription page with a free trial as the main action, was built three ways for this comparison on November 4, 2026: no skill, Hallmark, and Impeccable. Agents read each skill's SKILL.md file rather than running a live install, nothing was rendered, and both checkers were run against all three outputs. The sample is one brief, so the value here is in the checker behaviour, not in a ranking.
| Condition | File size | sloplint (Hallmark checker) | Impeccable detector |
|---|---|---|---|
| No skill | 6,247 bytes | 13 fail, 14 reflex, 7 warn | 1 finding |
| Hallmark | 19,742 bytes | 0 fail, 0 reflex, 0 warn | 3 findings |
| Impeccable | 23,921 bytes | 15 fail, 28 reflex, 5 warn | 9 findings |
Each build is clean only under its own definition. The Hallmark build passed sloplint completely, yet the Impeccable detector still found 3 issues in it, two for insufficient spacing and one for a cream background. The Impeccable build kept 9 findings under its own detector, and the no skill build, which failed sloplint 13 times, drew only a single detector finding, the same cream background. The two checkers maintain different lists of what an AI generated look consists of, which is why a checker score cannot be read as a quality ranking between the skills.
Each build is clean only under its own checker. The two tools do not share one definition of an AI generated look.
Two details from the run reinforce the outside reviews. The font problem AI Parabellum reported reproduced here: the Hallmark build followed its Vellum theme into a blackletter headline font, Grenze Gotisch, which shows how strongly a theme steers the result. And only the Hallmark build used real photos, two of them with sources credited, while the other builds shipped no images at all. One of the Impeccable findings also held up to arithmetic: a low contrast pair, body text at #5c4630 on a #241509 background, works out to a 2.0:1 contrast ratio. The remaining findings were spacing judgements that need a rendered page to settle. File size points the same way as the Hallmark cost reports, at about 3.2 times the no skill build for Hallmark and 3.8 times for Impeccable.
Choosing by Job
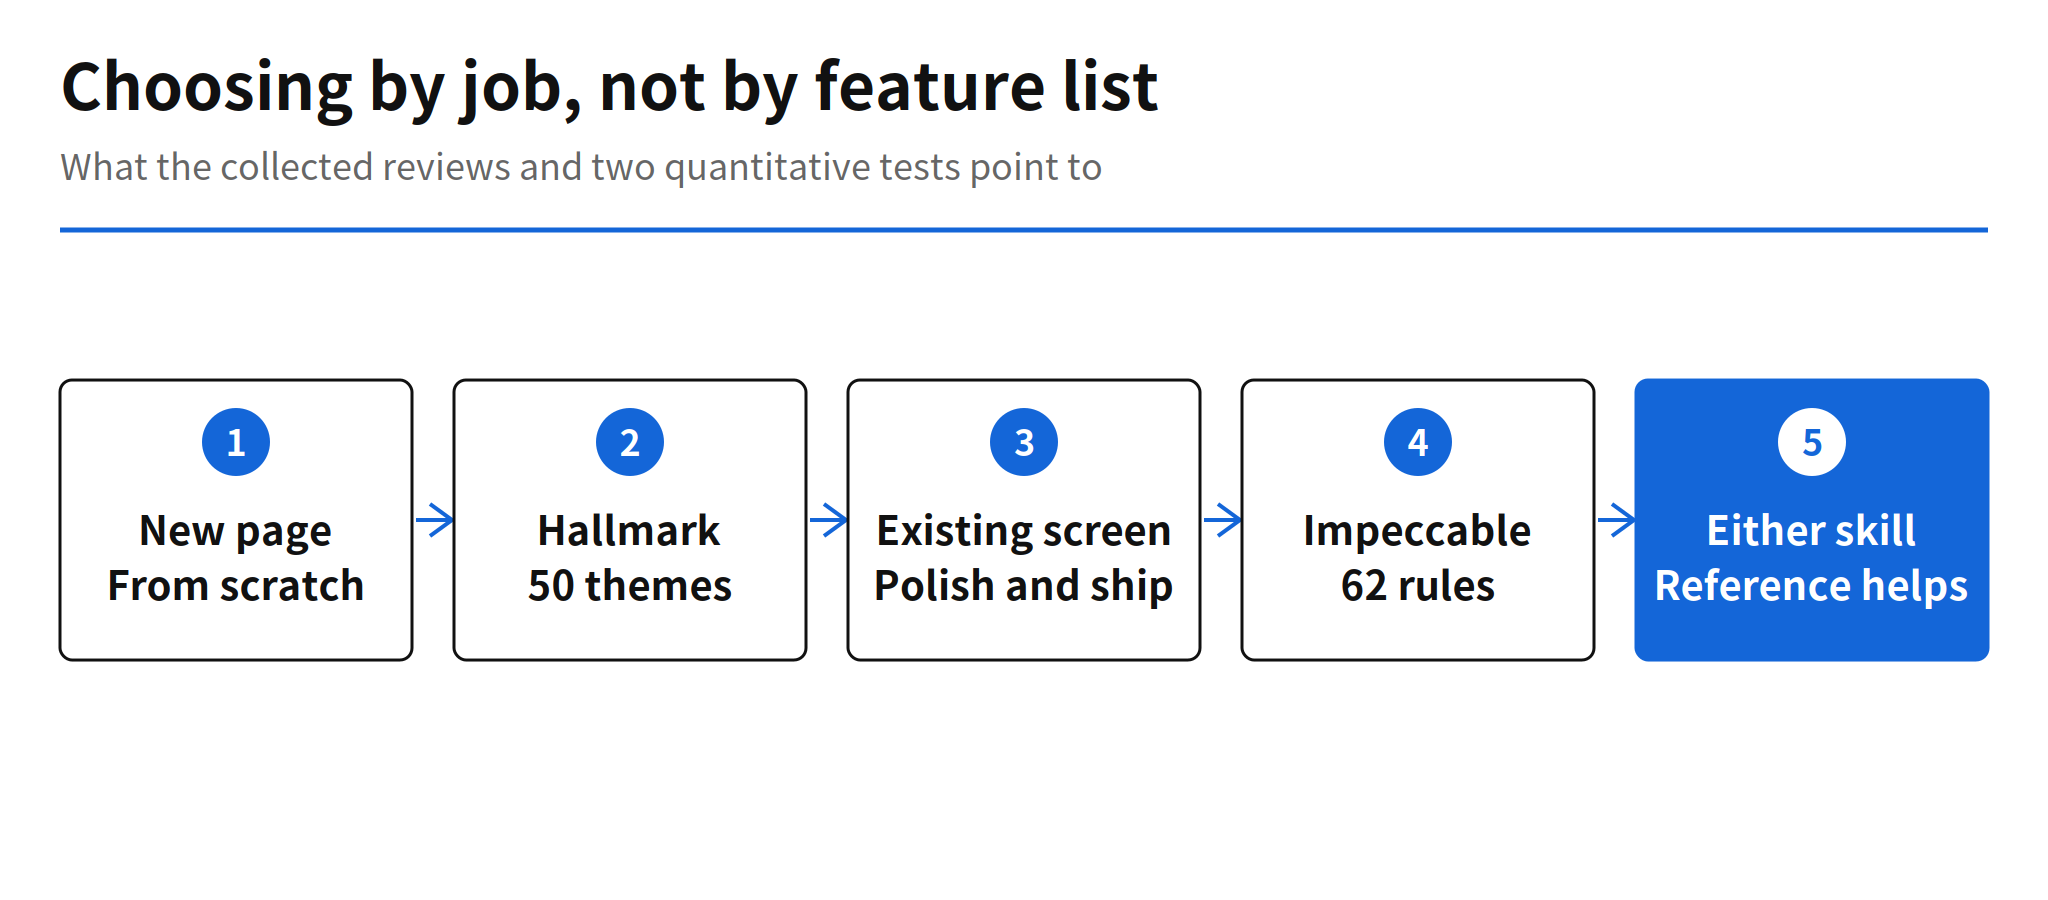
- New landing page: Hallmark. The first screen improvement is the one result with a measured before and after (AI Parabellum), and the user reviews collected by the curator agree. Budget for the slower, more expensive build.
- Existing screen: Impeccable. The accessibility drop from 106 violations to 0 is measured, most collected reviews say the same, and the README itself names this as the strongest use.
- Either skill: attach a reference. Reviewers repeated that a screenshot of the target look mattered more than the choice between skills. The Medium test notes the same pattern from the other side: the brief, not the tool, decided much of the outcome.
npx skills add nutlope/hallmark -g
npx impeccable install
What the Tests Cannot Show Yet
- One quantitative test per skill. Every headline number in this post rests on a single outside test, plus one single brief head to head run. None of the figures should be treated as a general average yet.
- Unverifiable review layer. The Threads curator collected user reviews without links to the originals, so that layer is one person summary. The two quantitative tests do not share that problem.
- Checker scores are self graded. A sloplint pass certifies compliance with Hallmark rules. It is not an independent measure of page quality, and the head to head run shows the scores do not transfer across tools.
- Mixed reports on visible difference. Some collected reviews say the outputs end up looking similar, and one user rebuilt a homepage and preferred the original design. The blind review disagreed for Impeccable. Whether the gap grows or shrinks seems to depend on the starting point and on how the result is judged, and that condition split is not mapped yet.
The wider pattern is a shift in how agent skills get chosen. A few weeks of trending design skills, including unslop and taste-skill, were covered on feature lists alone. This comparison is the first collected evidence priced in time, cost, and defect counts, and it fills the independent verification gap that the original Hallmark and Impeccable write ups both left open. The practical rule that survives the caveats is simple: pick by the job in front of the agent, new page or existing screen, and treat any single checker score as a house rule check, not a verdict.
Related Reading
For the release this comparison builds on, see Hallmark v2 Design Skill: 50 Themes for Coding Agents, covering the version 2 expansion to 50 themes and the redesign and audit commands. That post noted the absence of independent verification of page quality. The tests gathered here are the first answer to it.
FAQ
Which skill is better for a new landing page, Hallmark or Impeccable?
The collected reviews point to Hallmark for building a new landing page from scratch. In the AI Parabellum test, small caps eyebrow labels dropped from 6 to 0 and real credited photos replaced empty image boxes. The trade was time and cost, with build time rising from 44 seconds to 3 minutes 32 seconds and estimated cost from $0.16 to $0.87.
Which skill is better for fixing an existing screen?
The collected reviews point to Impeccable for polishing an existing screen before shipping. In the Medium test by AI Pruner, accessibility violations on a dental admin page fell from 106 with no skill to 0 with Impeccable installed. Most user reviews collected by the Threads curator gave the same verdict, and the Impeccable README describes this as its strongest use.
Can checker scores rank Hallmark and Impeccable against each other?
No. In a head to head test run for this comparison, the Hallmark build passed its own sloplint checker completely but still drew 3 findings from the Impeccable detector, while the Impeccable build kept 9 findings under its own detector. Each skill defines a different list of what counts as an AI generated look, so a clean score only means clean under that skill's own rules.
How large are the test samples behind this comparison?
Small. Each skill has one quantitative test from an outside author, the Medium test covered two pages, and the head to head run covered one brief. The numbers show direction for each use case, not general averages, and no test has yet run the same task through both skills under one shared scoring method.